UK AI Security Institute opens benchmark results for reproducible evaluation
The UK AI Security Institute publicly releases verified evaluation results for six frontier models across five benchmarks using EvalEval's infrastructure.

Published
September 22, 2026
Reading time
4 minutes
Perspective
Research
Topics
benchmark reproducibility · structured LLM outputs · AI safety assessment
The UK AI Security Institute (AISI), in collaboration with the EvalEval Coalition, has released detailed evaluation results for six frontier models—Claude Opus 4, Claude Opus 4.5, Claude Opus 4.6, GPT-5, GPT-5.2, and GPT-5.4—on five benchmarks: HealthBench, FrontierMath, Humanity's Last Exam, SWE-Bench Pro, and Terminal-Bench 2.0. These results include configuration data, context, and verified outcomes, published via Evaluation Cards under the Every Eval Ever schema. The release supports reproducibility by making evaluation protocols and inference compute dependencies transparent, addressing prior issues of opaque reporting in AI evaluation.
AISI publishes benchmark results with full evaluation context
AISI released verified results for six frontier models across five benchmarks, including Terminal-Bench 2.0 and Humanity's Last Exam, with full metadata on evaluation protocols and inference compute usage. The data accompany the paper 'How Inference Compute Shapes Frontier LLM Evaluation,' showing that performance varies with token limits and feedback mechanisms. This transparency enables direct comparison between evaluations and reduces ambiguity caused by unreported setup differences.
Source: How UK AISI and EvalEval Are Making Benchmark Results Reproducible · Hugging Face Blog
llm-typesafe plugin enables structured outputs from Jev model
Simon Willison released llm-typesafe 0.1a0, a plugin enabling structured yes/no, choice, and scoring outputs from TypeSafe AI's Jev model. Users can query models with explicit criteria, such as 'Does this message explicitly request a refund?' and receive structured JSON responses like {"type": "noul", "noul": 0.99}. This allows deterministic, rule-bound interactions with LLMs, bypassing open-ended generation for safety-critical classification tasks.
Source: llm-typesafe 0.1a0 · Simon Willison
TikTok content analysis identifies absence of voice as AI indicator
In a post quoted by Simon Willison, @therealcornpop observes that AI-generated TikTok scripts lack a definitive personal voice, exhibiting repetitive punctuation, staccato phrasing, and superficial depth. The key signal is not stylistic quirks but the absence of authentic opinion or subjective perspective. This observation aligns with prior claims that AI-generated content often reflects pattern mimicry without grounded intent or personal conviction.
Source: Quoting @therealcornpop · Simon Willison
Community explores gzip as a primitive language classifier
Hacker News users discussed using gzip compression ratios to classify text by topic or language, citing Witten’s group and the Hutter Prize. One user described seeding gzip dictionaries with Wikipedia articles to detect language by compression efficiency. Others noted this mirrors tokenization in LLMs, with Byte Pair Encoding (BPE) being a more refined version. The method remains a heuristic, not a model, and lacks scalability for multilingual or domain-specific contexts.
Source: Can gzip be a language model? · Hacker News
Poitras Center launches 50 fellowships for psychiatric disorders research
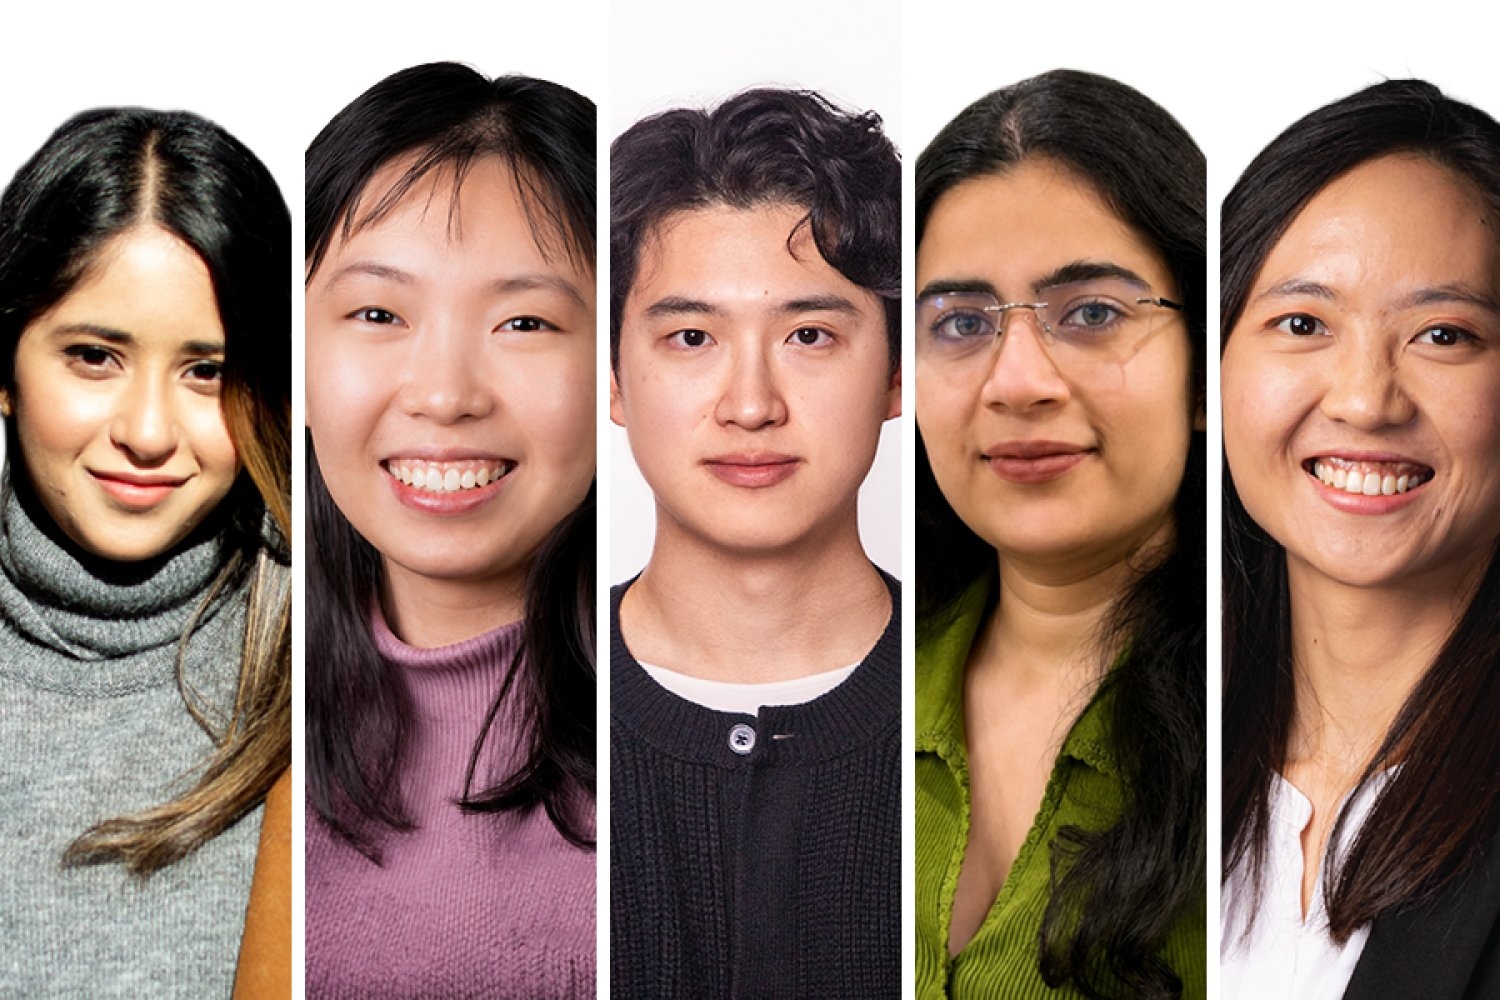
Patricia and James Poitras established 50 two-year fellowships for MIT graduate students and postdocs through the Poitras Center for Psychiatric Disorders Research. The $10 million gift supports five fellows annually for a decade, focusing on mental illness research including anxiety, schizophrenia, and bipolar disorder. Inaugural fellows are studying neural circuits of fear memory, gut-brain communication in depression, and AI-based prediction of treatment response.
Source: Poitras Center to fuel early careers of 50 young scientists dedicated to psychiatric disorders research · MIT News · AI
OpenAI publishes principles for third-party AI safety assessments
OpenAI announced priorities and principles for conducting rigorous, secure, and independent third-party safety assessments of frontier models and safeguards. The announcement, made via its official channel, emphasizes the need for transparency and autonomy in evaluation processes but does not specify technical requirements, audit scopes, or access protocols. No implementation timeline or external validation criteria are provided.
Source: Priorities and principles for effective third party assessments · OpenAI News
What to watch next
These developments collectively reflect growing institutional efforts to formalize evaluation practices in AI, from reproducible benchmarking and structured model outputs to foundational research funding. The release of AISI’s evaluation data and the Jev plugin represent concrete steps toward verifiable, deterministic AI interactions, while the Poitras fellowships and OpenAI’s principles signal long-term investment in safety and scientific rigor. The gzip discussion underscores persistent interest in compression-based heuristics as low-cost proxies for linguistic analysis.
Continue reading