Offloaded inference and GPU-accelerated simulation advance physical AI
Microsoft Research demonstrates that offloading AI inference from robots to edge/cloud GPUs improves task success, battery life, and scalability, while.
Published
September 23, 2026
Reading time
4 minutes
Perspective
Research
Topics
robotics inference · GPU simulation · text-to-speech
In September 2026, two critical developments in physical AI infrastructure emerged: Microsoft Research validated that moving inference offboard from robots to remote GPUs significantly enhances performance and operational endurance, and Hugging Face detailed how NVIDIA Warp and MJWarp enable massive parallelization of MuJoCo-based robotics simulations on NVIDIA GPUs. These advances address systemic bottlenecks in real-world robotics—onboard compute limitations and simulation scalability—without altering robot hardware or AI model architectures. Both efforts focus on systems-level optimization, emphasizing distributed compute and efficient resource orchestration over hardware upgrades.
Offloading inference improves robot task success and battery life
Microsoft Research’s study on mobile manipulation tasks showed that offloading AI inference from onboard GPUs to edge or cloud GPUs increased task success rates, reduced response delays, and extended robot battery life by up to 160% when replacing Jetson Thor with a Raspberry Pi-5. Onboard GPUs limited model capacity, causing up to 383% slowdown in mapping and planning, and 50% accuracy loss in VLA models. The research confirmed that remote inference enables deployment of larger models without increasing robot weight or power draw, directly improving performance in dynamic environments.
Source: Offloaded inference for real-world physical AI robotics · Microsoft Research
MJWarp enables GPU-scale robotics simulation with 2,048 parallel environments

Hugging Face demonstrated that MuJoCo Warp (MJWarp), built on NVIDIA Warp, can simulate up to 2,048 independent robot environments simultaneously on a single GPU. By compiling MuJoCo physics into CUDA kernels, MJWarp achieves batched state advancement without altering the original MJCF model format. This allows researchers to scale simulation throughput for reinforcement learning without switching simulation frameworks, maintaining compatibility with existing assets while drastically reducing the time required to collect training data across diverse scenarios.
Source: How to Use NVIDIA Warp and MjWarp to Accelerate Robotics Simulation and Learning Workflows · Hugging Face Blog
Gemini 3.8 TTS models enable granular voice control and long-form audio generation

Google DeepMind introduced Gemini 3.8 Flash TTS and Flash-Lite TTS, which allow users to generate custom voices from natural language prompts and direct performance line-by-line with cues like <laughs> or |mhm|. These models support long-form audio with minimal speaker drift, enable native two-speaker dialogue staging, and achieved top rankings on Hume AI’s Voice Design Benchmark and Overall Quality Index. Built-in watermarking and consent verification are included, but no metrics on latency, token throughput, or multilingual latency were disclosed.
Source: Gemini 3.8 text-to-speech says hello · DeepMind Blog
GPT-6 Luna and Sol cut pricing by 50% compared to GPT-5.6 equivalents
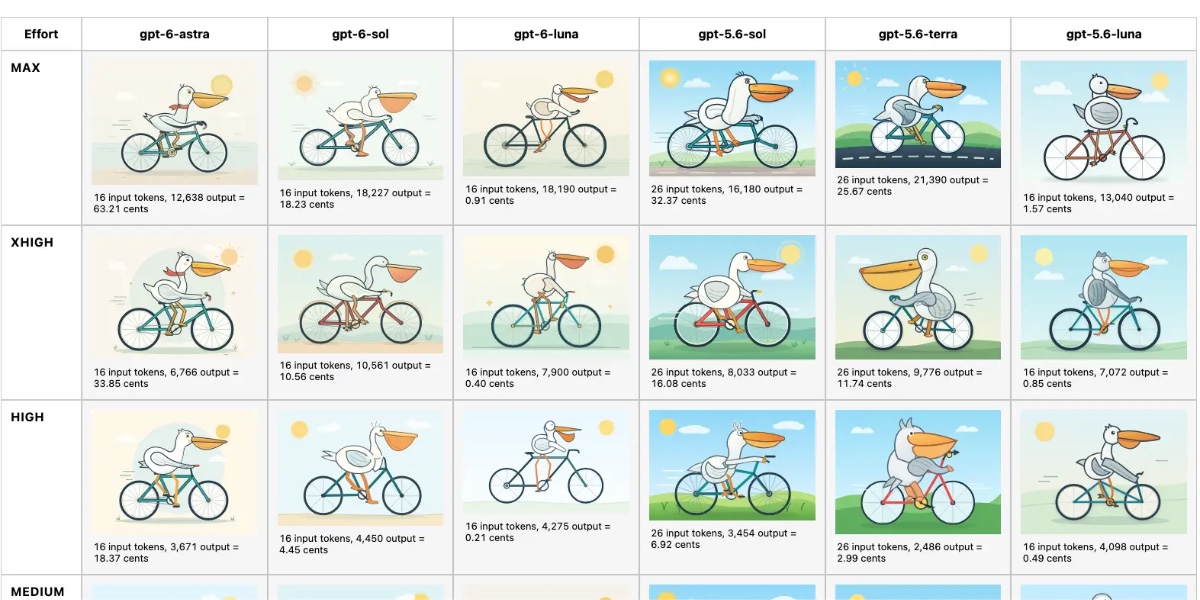
OpenAI released GPT-6 Sol and GPT-6 Luna at half the price of their GPT-5.6 predecessors, with Luna priced at $0.10/M input and $0.50/M output. This makes Luna the cheapest high-performance model OpenAI has ever released, undercutting Grok 4.7 and Claude Opus 5.5. Anthropic reduced Opus 5.5 pricing by 20%, but its cost remains significantly higher than GPT-6 Luna. No performance benchmarks or latency metrics were provided to correlate price reductions with capability changes.
Source: Claude Opus 5.5, GPT-6 Sol, GPT-6 Luna, and a new price war · Simon Willison
llm 0.36 adds support for GPT-6 Sol and Luna, enforces single-turn model constraints
The llm command-line tool version 0.36 added native support for GPT-6 Sol and GPT-6 Luna via new model identifiers. It introduced a new flag, supports_conversation = False, to block multi-turn interactions with models that only accept single prompts. The tool now wraps reasoning traces in <details><summary> tags for better log readability. These changes reflect ecosystem adaptation to new model capabilities, not model architecture updates.
Source: llm 0.36 · Simon Willison
Jun Kim joins Hugging Face to lead MLX development

Jun Kim, creator and maintainer of oMLX, joined Hugging Face to advance MLX, Apple’s framework for local AI on Apple Silicon. Hugging Face confirmed oMLX will remain Apache 2.0 and under Jun’s leadership, with plans to streamline conversion from Hugging Face transformers models to MLX-compatible implementations. Kim noted his GitHub account was suspended post-announcement, suggesting potential platform-level friction, though no resolution was provided.
Source: Jun Kim, oMLX creator and maintainer, joins Hugging Face to support the MLX community · Hugging Face Blog
What to watch next
These developments collectively highlight a maturation of physical AI infrastructure: systems-level optimizations in inference distribution, simulation scaling, and local compute are becoming as critical as model innovation. The pricing shifts in LLMs and the integration of specialized frameworks like MLX and MJWarp indicate growing ecosystem specialization, where performance gains are increasingly derived from software orchestration rather than hardware alone.
Continue reading